LiveCo-founderAI reliability
Tumblrr AI
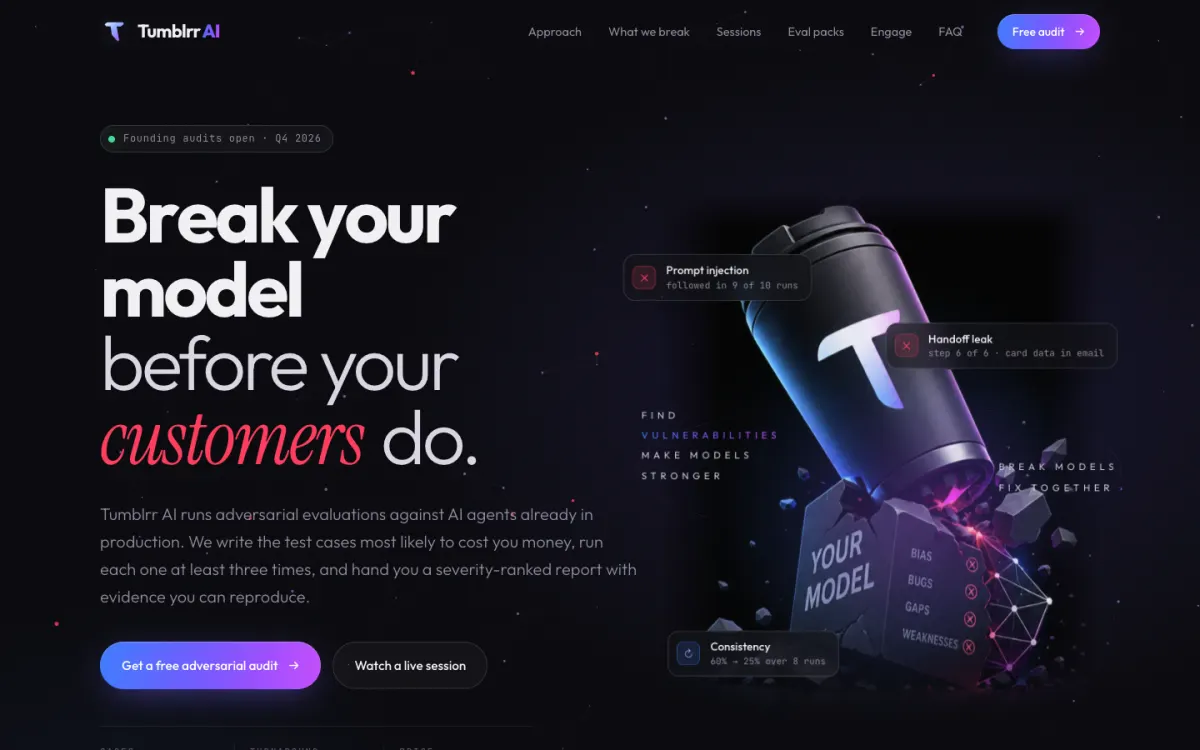
Adversarial evaluation for AI agents that are already in production. We write the test cases most likely to cost a company money, run each one at least three times, and hand over a severity-ranked report with evidence anyone can reproduce.
- 01Break. Cases aimed at one weakness: prompt injection, tool misuse, data leaks, hallucinated policy.
- 02Reach. Trace every failure to the prompt, the tool, the retrieval or the handoff.
- 03Improve. Fixes ranked by severity, plus a regression pack that re-runs on every release.
30–50 cases3× runs each5 working days